VSL A/B testing: what to test first, how much traffic you need, and how to call a winner
A practical system for VSL A/B testing: which elements to test first, how to set up a fair split, how much traffic a test really needs, how to read significance without fooling yourself, and how to judge winners by revenue per visitor.
On this page
- What should you A/B test in a VSL first?
- How do you set up a fair VSL split test?
- Which metric should decide a VSL A/B test?
- How many visitors does a VSL A/B test need?
- How do you know if a split test result is significant?
- Why peeking at results breaks a VSL test
- Folder split, smart split or variant tests: which should you use?
- How should you document VSL tests?
- Common VSL A/B testing mistakes
- Your next 30 days of VSL testing
- Frequently asked questions
VSL A/B testing means sending comparable visitors to two versions of a video sales letter that differ in one thing, then keeping the version that earns more revenue per visitor once the gap is unlikely to be chance. Test the big levers first (offer, lead, big idea, pitch, price), decide the sample size before you start, and don't stop early because one version is ahead.
What should you A/B test in a VSL first?
Test what buyers decide on before what they barely notice. The offer and the lead change who buys and how many people hear the pitch; a button color changes neither. Small tweaks are cheap to build, but small effects need enormous samples to measure, as the math below shows. Here is a starting order, from the biggest levers down:
What to test first, in order of impact
- Offer: bundles, bonuses, guaranteeWhy it moves revenue: changes what people decide on. Judge by: RPV, refund rate.
- Lead: the first one to three minutesWhy it moves revenue: decides how many people hear the argument. Judge by: 1-minute retention, pitch reach, RPV.
- Big idea or angleWhy it moves revenue: changes who believes the story. Judge by: RPV.
- Pitch and closeWhy it moves revenue: turns pitch viewers into clickers. Judge by: CTA clicks per pitch viewer, RPV.
- PriceWhy it moves revenue: trades conversion rate against order value. Judge by: RPV, average order value.
- Page and player: headline, poster, speed, CTA timingWhy it moves revenue: cheap and quick, usually smaller effects. Judge by: play or unmute rate, pitch reach, RPV.
Treat this order as a starting point, not a law. If your retention graph shows half the audience leaving in the first 90 seconds, the lead jumps to the top whatever the order above says. Price tests need care: a lower price can lift conversion rate and still lower RPV, and a higher one can do the reverse.
How do you set up a fair VSL split test?
A test is only as good as its comparison. These rules keep the two groups comparable:
- Change one thing, or one coherent package. A whole new lead counts as one change. A new lead plus a new price is two, and you won't know which one moved the result.
- Assign visitors at random and keep them there. A returning visitor must see the version they saw first; otherwise people see both and the groups blur. RevvyScales folders split traffic between VSLs by weight, with assignment per new visitor and sticky (folders and A/B splitting).
- Run both versions at the same time on the same traffic. Never compare this week's version B with last month's version A. Ads, audiences and seasons shift underneath you.
- Split 50/50 when you can. Unequal splits cost traffic. Precision depends on 1 ÷ (visitors in A) + 1 ÷ (visitors in B), which is smallest when the groups are equal. With an 80/20 split you need about 56% more total visitors than with 50/50; with 90/10, nearly 2.8 times as many.
- Run whole weeks. Start and stop on the same weekday, with at least one full week and usually two, so weekday and weekend buyers are both in the sample.
- Freeze everything else. No new ads in the test's traffic, no price edits, no page tweaks. If something must change, restart the count.
- Write the plan first. Hypothesis, primary metric, guardrails, smallest lift worth detecting, sample size and end date. A test without a plan turns into a search for a story.
Here is a folder split between two VSLs at equal weights, with revenue per visitor beside each:
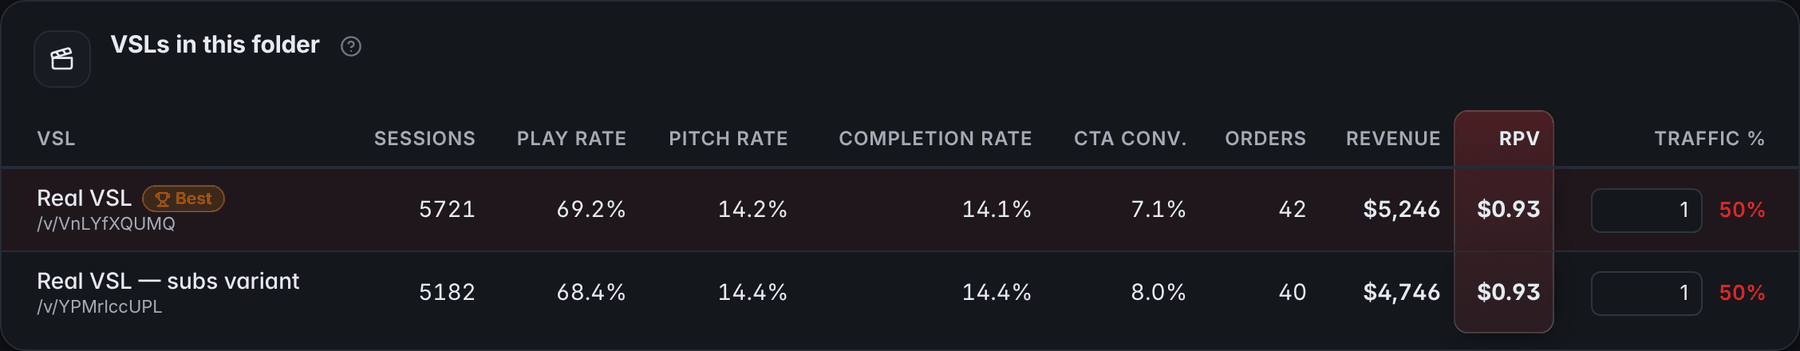
- RPVRevenue per visitor for each version: the metric to decide on.
- Traffic %Each VSL's weight sets its share of new visitors, who stay on the version they first saw. Equal weights give a 50/50 split.
Which metric should decide a VSL A/B test?
Decide on revenue per visitor: total revenue from the variant, upsells included, divided by its unique visitors. RPV combines conversion rate and order value, so a change that pushes more people toward the cheapest option can't fake a win. The revenue per visitor guide covers the formula and its variants, and the VSL metrics guide shows where it sits in the full metric tree.
Everything upstream is a diagnostic. Play rate, retention, pitch reach and CTA clicks explain why a variant won or lost, and they react faster than revenue, but they don't pay for media. Pick a few guardrails as well: refund rate, average order value and checkout conversion (orders ÷ CTA clicks). A variant that wins on RPV but doubles refunds hasn't won.
A worked example shows why. Two versions get 10,000 visitors each:
Two versions, 10,000 visitors each
Worked example
Higher RPVVersion A
- Reached the pitch: 2,200
- CTA clicks: 300
- Orders: 180
- Average order value: $80
- Revenue: $14,400
- RPV: $1.44
Wins upstreamVersion B (earlier, simpler pitch)
- Reached the pitch: 2,600
- CTA clicks: 380
- Orders: 185
- Average order value: $76
- Revenue: $14,060
- RPV: $1.41
B beats A on pitch reach by 18% and on CTA clicks by 27%, then loses on revenue, because its simpler pitch steered more buyers to the single-unit option. Judged on upstream metrics alone, you would have shipped the worse version.
How many visitors does a VSL A/B test need?
Four things set the sample size: your baseline conversion rate, the smallest lift you want to be able to detect, the confidence level (95% is the usual standard) and statistical power (80% is common, meaning an 8-in-10 chance of detecting a real lift of that size).
Evan Miller gives a handy rule of thumb in How Not To Run an A/B Test: visitors per variant n = 16σ² ÷ δ², where δ is the smallest difference you want to detect and σ² is the variance. For a conversion rate p, σ² = p × (1 − p). The 16 is 2 × (1.96 + 0.84)² ≈ 15.7 rounded up, built from the z-values for 95% confidence and 80% power. For low conversion rates it simplifies to something you can do in your head:
Rule of thumb
Sales needed per variantabout 16 ÷ (relative lift)²
To detect a 20% lift: 16 ÷ 0.2² = 400 sales per variant. A 10% lift needs about 1,600.
The shortcut runs slightly low, so treat it as a floor. Here's the exact calculation at a 2% baseline conversion rate, 95% confidence (two-sided) and 80% power:
| Smallest lift to detect | Conversion rates | Visitors per variant | Sales per variant (baseline arm) |
|---|---|---|---|
| 10% | 2.0% → 2.2% | about 80,700 | about 1,600 |
| 20% | 2.0% → 2.4% | about 21,100 | about 420 |
| 30% | 2.0% → 2.6% | about 9,800 | about 200 |
| 50% | 2.0% → 3.0% | about 3,800 | about 77 |
Now turn that into days. Say your VSL gets 1,500 visitors a day. Detecting a 20% lift needs about 42,200 visitors in total, roughly 28 days. Detecting a 30% lift needs about 19,600, roughly 13 days, which you'd round up to two full weeks. Halving the lift you can detect roughly quadruples the traffic you need, so a smaller account should test bold changes that could plausibly move results by 30% or more, not new button colors.
Try it with your own numbers. The calculator uses the same 95% confidence and 80% power, and starts with the 20% example at 1,500 visitors a day:
Calculator
A/B test sample size calculator
How many visitors each version needs before a difference in conversion rate means something.
- Visitors in all
- Days at your traffic
- Orders per version at the current rate
95% confidence and 80% power, the usual defaults for comparing two conversion rates. Fix the sample before you start and read the result when it is reached: stopping the moment one version pulls ahead finds winners that aren’t there. With more than two versions, each is compared with the control and needs this many visitors.
RPV needs at least as much traffic as conversion rate, usually more. Each visitor's revenue is either zero or an order value, and when order values vary (bundles, upsells) the noise grows. A practice rule: before you call an RPV winner, remove the single largest order from each arm and check the winner still wins.
How do you know if a split test result is significant?
Significance measures how often random assignment alone would produce a gap this large if the two versions were truly identical. At 95% confidence you accept a winner only when that would happen less than 5% of the time.
For conversion rates the standard tool is the two-proportion z-test (NIST's description). In plain steps:
The two-proportion z-test
Pool the groups, then work out the standard error and z
Pooled ratetotal sales ÷ total visitors
Standard error√(pooled rate × (1 − pooled rate) × (1 ÷ visitors in A + 1 ÷ visitors in B))
z(rate B − rate A) ÷ standard error
Example 1, a small test. A: 2,000 visitors, 40 sales (2.0%). B: 2,000 visitors, 52 sales (2.6%). That's a 30% lift on paper. Pooled rate = 92 ÷ 4,000 = 2.3%. Standard error = √(0.023 × 0.977 × 0.001) ≈ 0.47 percentage points. z = 0.6 ÷ 0.47 ≈ 1.27. Not significant: a gap this size would show up by chance about one time in five.
Example 2, a larger test. A: 12,000 visitors, 240 sales (2.0%). B: 12,000 visitors, 300 sales (2.5%). Pooled rate = 540 ÷ 24,000 = 2.25%. Standard error ≈ 0.19 points. z = 0.5 ÷ 0.19 ≈ 2.61. Significant at 95% (p ≈ 0.009).
Even in example 2, the true lift isn't exactly 25%. The 95% confidence interval for the difference is about 0.5 ± 0.375 points, so the real lift could be anywhere from roughly 6% to 44%. Significance tells you B is very probably better, not by how much. Plan your economics on the conservative end.
Keep the base rate in mind too. At 95% confidence, a test of a change that does nothing still produces a false winner 5% of the time. Run 20 such tests and you should expect about one false winner.
Why peeking at results breaks a VSL test
The 95% math assumes you look once, at a sample size chosen in advance. Checking every day and stopping the first time the dashboard says "significant" gives chance many extra attempts. In Evan Miller's worst-case illustration, where significance is checked after every observation and the change does nothing, the real false-positive rate reaches 26.1%, more than five times the 5% you thought you had.
Three ways to handle it:
Three ways to handle peeking
Fixed horizon
Set the sample size and end date in the plan, watch the dashboard only for broken tracking, and decide once.
Methods built for monitoring
Sequential and Bayesian designs are made for checking as you go. Use a tool that implements one properly rather than eyeballing a p-value.
Adaptive allocation
When earning during the test matters more than measuring the exact gap, shift traffic toward the leader as evidence builds: the "multi-armed bandit" approach, which trades exploration of uncertain options against exploitation of the current best (overview).
You give up a precise estimate in exchange for less money spent on the loser.
Folder split, smart split or variant tests: which should you use?
Answer one or two questions to find the setup that fits your test:
Folder split, smart split or variants?
Four options in RevvyScales, and what each is for
What are you testing?
Do you need a clean answer, or traffic kept on the best?
Best fit
Folder split (every plan)
Fits when: you're testing whole VSLs (an offer, lead, angle or price test) and need a clean answer. How traffic moves: fixed weights between whole VSLs, sticky per visitor. Trade-off: the loser keeps its share until you stop.
Best fit
Smart traffic split (Growth+)
Fits when: you're running whole VSLs and want to keep traffic on the best of several proven ones. How traffic moves: it shifts traffic toward the VSLs earning the most per viewer, judged on complete days. Trade-off: you get a winner, not a clean estimate of the gap.
Best fit
Headline, poster and speed variants (Growth+)
Fits when: you're running page and player tests (headline, poster or speed) without duplicating the VSL. How traffic moves: variants inside one VSL, shown by weight, sticky per viewer. Trade-off: limited to those elements; you call the winner.
Best fit
Offer variants (Growth+)
Fits when: you're running price and bundle tests without duplicating the VSL. How traffic moves: bundles, prices or offer headlines by weight inside one VSL, sticky per viewer. Trade-off: it tests the offer, not the video.
Variant tests inside one VSL follow the same discipline as a folder split: set the weights, let the planned sample build, then read the per-variant breakdown in analytics and decide (split-testing your offers, playback-speed A/B test). Smart traffic split behaves more like a bandit (smart traffic split): use it once a folder holds versions you'd be happy to run, not to settle one big question. Playback speed is a test with its own trade-offs, covered in VSL playback speed.
How should you document VSL tests?
Without a log, teams re-run old losers and can't explain why a past winner worked. Keep one entry per test:
| Field | Example |
|---|---|
| Test name | 2026-10 lead test: story vs warning |
| Hypothesis | Cold traffic needs the problem named in the first 10 seconds, so a warning lead will lift 1-minute retention and RPV |
| Variants | A: story lead (control). B: warning lead, same body |
| Primary metric | RPV |
| Guardrails | Refund rate, average order value, checkout conversion |
| Smallest lift worth detecting | 25% |
| Sample size and end date | About 280 sales per arm at a 2% baseline (about 13,800 visitors each), whole weeks |
| Traffic | Meta prospecting, all placements, US |
| Result | A $1.38 vs B $1.71 RPV, significant at 95% on conversion rate |
| Decision and learning | Ship B; test warning-style hooks in the ads next |
Over time the log becomes your playbook: patterns appear in which kinds of changes move your audience and which don't.
Common VSL A/B testing mistakes
- Stopping at the first significant reading. Decide the sample size first and wait for it.
- Testing small tweaks on small traffic. If you can't detect less than a 30% lift, don't test changes that could only move results by 5%.
- Declaring winners on CTA clicks or conversion rate alone. Use RPV, with guardrails.
- Changing traffic mid-test. A new ad set or audience changes who's in the test. Restart.
- Slicing until something wins. "B won on iPhones in Texas", found after the fact, is a false-positive machine. Name any segment you care about in the plan.
- Non-sticky assignment. If visitors can see both versions, the groups blend and real differences shrink.
- Forgetting the back end. Watch refunds and chargebacks for a few weeks after an offer "wins".
- Never re-testing. When a win is surprisingly large, confirm it with a second run, or keep a small share of traffic on the old version for a while.
Your next 30 days of VSL testing
Tick these off as you go; the ticks stay in this browser:
Your next 30 days
0 of 7 done
Frequently asked questions
How long should a VSL split test run?
Until it reaches the sample size you planned, and in whole weeks: at least one full week, usually two, starting and ending on the same weekday. Calculate the sample from your baseline conversion rate and the smallest lift you care about. If that would take more than about a month of traffic, test a bolder change rather than running the test longer.
Can you A/B test a VSL with low traffic?
Yes, if you test big changes. With few visitors you can only detect large lifts, so test the offer, the lead or the angle rather than small page details. A rule of thumb is 16 divided by the squared relative lift for the sales needed per variant: about 64 sales each to detect a 50% lift. Use pitch reach as an early signal, but confirm on revenue.
What confidence level should I use for VSL tests?
95% is the usual standard and a sensible default. Dropping to 90% cuts the sample you need by about a fifth, but it doubles the share of false winners you accept when nothing really changed, from 5% to 10%. Some teams accept that for cheap, easily reversed page changes. For offers, prices and full re-edits, keep 95% and the planned sample size.
What is the difference between A/B testing and multivariate testing?
An A/B test compares whole versions that differ in one element or one package of changes. A multivariate test changes several elements at once and measures every combination, for example three headlines times two posters, which makes six versions. Each combination needs its own sample, so multivariate tests need far more traffic. For most VSL funnels, one A/B test at a time on high-impact elements is the practical choice.
Can I run more than one VSL test at the same time?
Yes, if each test gets its own traffic or visitors are assigned to each test independently, but overlapping tests on the same visitors can interact: a new headline might only work with the new lead. The simplest safe setup is one test per traffic stream at a time. If you must overlap, keep the tests on unrelated elements and check results for each combination before shipping both winners.
Why did my winning VSL variant stop winning?
Common causes are a false positive from stopping early, a change in traffic such as new audiences, placements or creatives, or a real win that was smaller than it first looked. Check whether the test reached its planned sample and whether the traffic mix has changed since. If the win was large and surprising, re-run it against the old version on current traffic before rebuilding everything around it.